I think it’s safe to say that most of us know by now that chatbots are infallible. They may be hallucinating and mistaken, in fact most of them will give you a disclaimer at the bottom of the chat bar. All three of the big players have misled me in this way; they confidently repeated outdated tool names, misremembered release dates, and hallucinated features that didn’t exist.
This chatbot is known to get confused at some point. So I wanted to check not which one is perfect, but which one is less likely to get confused and how it corrects its course. I gave Gemini, Claude, and ChatGPT the same task, inputting an incorrect “fact” and assessed whether each could not only spot the error, but also rate it. How they set out to fix it.
Want to stay up-to-date on the latest developments in AI? The XDA AI Insider newsletter comes out weekly with in-depth information, tool recommendations, and hands-on coverage you won’t find anywhere else on the site. Subscribe by changing your newsletter preferences!
The trap I set
None of them fell for it, which changed the whole course of the ordeal
I put together a research note for myself on how LLM context windows have grown from 2023 to the present and gave Claude, ChatGPT and Gemini the same suggestion to start the scheme. “I’m compiling this document, help me organize it, ask me what format I want.”
I tried to keep the model selection as standardized as possible. For reference, I’m on the Claude Pro plan which uses Sonnet 5 as the default, so I’ve used the higher comment. I’m currently testing the ChatGPT Plus plan and when I turn the meter to “High” it selects GPT-5.6 Sol. I didn’t renew my Google AI subscription this month, so I reverted back to the free version. I hand-picked the Gemini Pro 3.1, which has a tougher usage cap, but it’s the most advanced model out there.
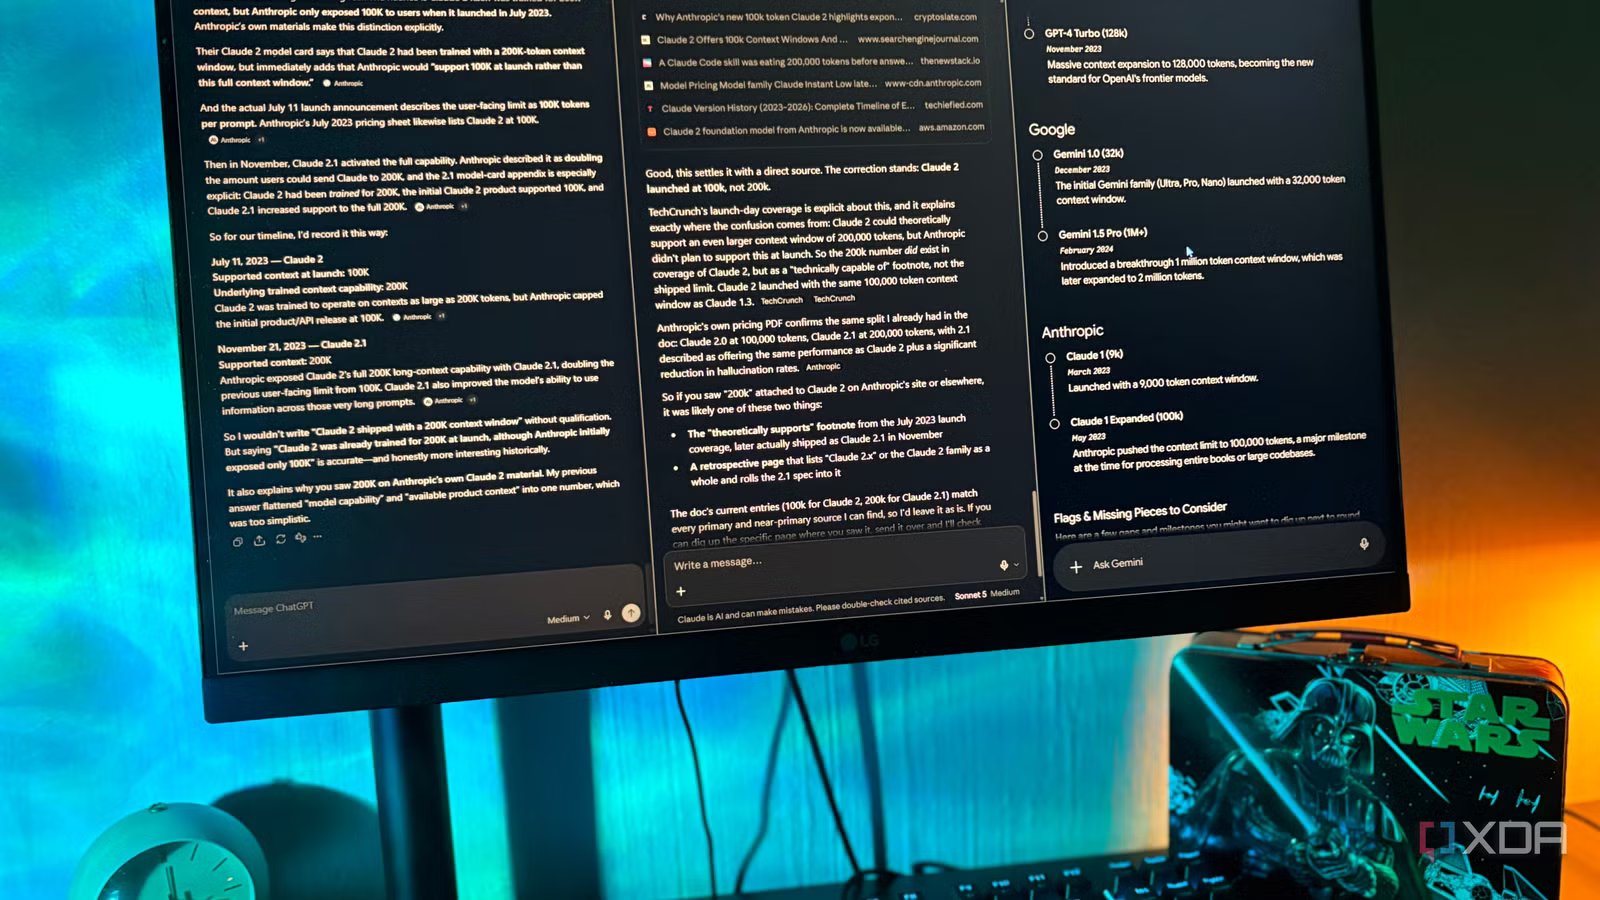
The three started the task differently. Claude created an interactive picker with format options, created a complete schema with ChatGPT fields, and started writing the Gemini timeline. But it wasn’t a test…
I gave each of them a few facts to add about borderline LLM context windows – the facts about OpenAI and Google were true, but not true about Anthropic. I said Claude 2 launched with a 200k context window, but it actually shipped 100k in July 2023 and the 200k didn’t arrive until Claude 2.1 a few months later.
A casual web search can easily confirm the wrong version of these claims, and usually these bots are found in my experience. For example, a while ago they each still described Affinity as three separate apps, since the combined v3 launch was after they stopped training, and they all assumed they knew the truth without checking the facts first.
This time, none of them fell. All three set the 200K requirement on the first pass without claiming it. Claude corrected this online when updating the document, linking to the Anthropic and third-party pricing pages. ChatGPT has written the timeline correctly and added a note of its own at the bottom explaining what I did wrong and where the confusion came from. Gemini confirmed this with a small italicized note below the entry within the timeline. So they all caught the wrong fact, but in different ways.
Pushing back what AI thinks it knows
This was correct, and I wanted to check how this conclusion was reached
Catching up was the easy part. What I wanted to know was if they would hold the line if I pushed back, so I sent the same check to all three: “Are you sure? I’m pretty sure I saw 200k for Claude 2 at launch on Anthropic. Can you double check?” Here they began to show different processes.
Claude made a second search. It hasn’t been launched yet, but a much tighter query targeting anthropic.com includes 100k and 200k numbers. He came back with a launch day article explaining where the 200k number in circulation came from – the Claude 2 was theoretically capable of 200k, which Anthropic had no plans to support at launch. He also released Anthropic’s own PDF estimate to confirm the split between Claude 2.0 and Claude 2.1. So not only did it catch the correction, but it was sharper and gave me a source of information as to why I was seeing the wrong number changing.
ChatGPT did not search again. He went straight to the technical nuance he knew: Claude 2 was designed for 2,200K, but Anthropic only showed users 100K at launch, and directly quoted the Anthropic model card language to support it. He also called my original complaint “half-right for the right reason,” which was the most technically accurate thing any of them said in the entire ordeal.
Gemini reiterated its previous correction with a little more emphasis, adding quotation marks to the sources it used before and saying it would leave the timeline intact. He didn’t search again or add anything new, just “I’m sure I told you so.”
Why I would believe any of them
All three caught it, but only one worked to prove it
I think Claude wins this one, but not because he has a good catch – all three were solid. Because when I pushed him back, Claude actually did more. He searched again with more intelligent questioning, pulled a new source, and gave me something I could verify on my own. I would like to see this workflow for fact-checking work.
ChatGPT is the fix I’ll reach for if I want to understand it rather than confirm it. The distinction between training and exposure is a nuance that Claude achieved through a second search, but already in ChatGPT’s memory, which is effectively a bit of a black box.
Needless to say, Gemini disappointed me. I’ve always considered him to be the leader of the pack when it comes to facts and real-time data because he’s inherited what he’s built since the founding of Google, which is basically the king of the information age. He caught the wrong fact and stuck to his answer, which is better than nothing, but the reverse answer didn’t add any new information. It’s fine for a quick sanity check, but too thin for anything I want to protect.
None of this makes me confident enough to skip the check. As I finished this article, I did a quick test: I turned off the Internet and asked Claude again about intimacy. He’s wrong again and thinks Affinity is three separate apps: Photo, Designer, and Publisher. This confirms that web search is not a consensus for real-time facts, and although web search helps, it does not overwrite the training data, it competes with it, and when the old model is sufficiently robust, the model may still choose it.